Don't worry! The contents here will appear on the published page.
Gemini 4 Argon Just Took the #1 Spot in Accounting AI
John Iwuozor
Content Lead, Finance and Research
John Iwuozor
Content Lead, Finance and Research
John Iwuozor leads content, finance, and research at DualEntry. He writes for the people who actually close the books: controllers running month-end, CFOs weighing an ERP migration, accountants buried in reconciliations. Before DualEntry he spent five years covering B2B SaaS and fintech for Forbes Advisor, Ramp, and Infosecurity Magazine. He builds every piece on primary data, including benchmarks, practitioner interviews, and product testing, rather than recycled advice. He is also an avid chess player.
Learn about our editorial policies.
Last updated
October 14, 2026
Reviewed by

Summarize this article
Google has a new frontier model, and so far, it is the strongest accounting model we’ve tested.
Gemini 4 Argon became broadly available on October 13, with Google positioning it for complex, multi-step work across areas including finance, coding, legal, and cybersecurity.
We ran it through the DualEntry Accounting AI Benchmark to see how it actually performs on accounting work. The result: 91.1% accuracy, ranking #1 overall.
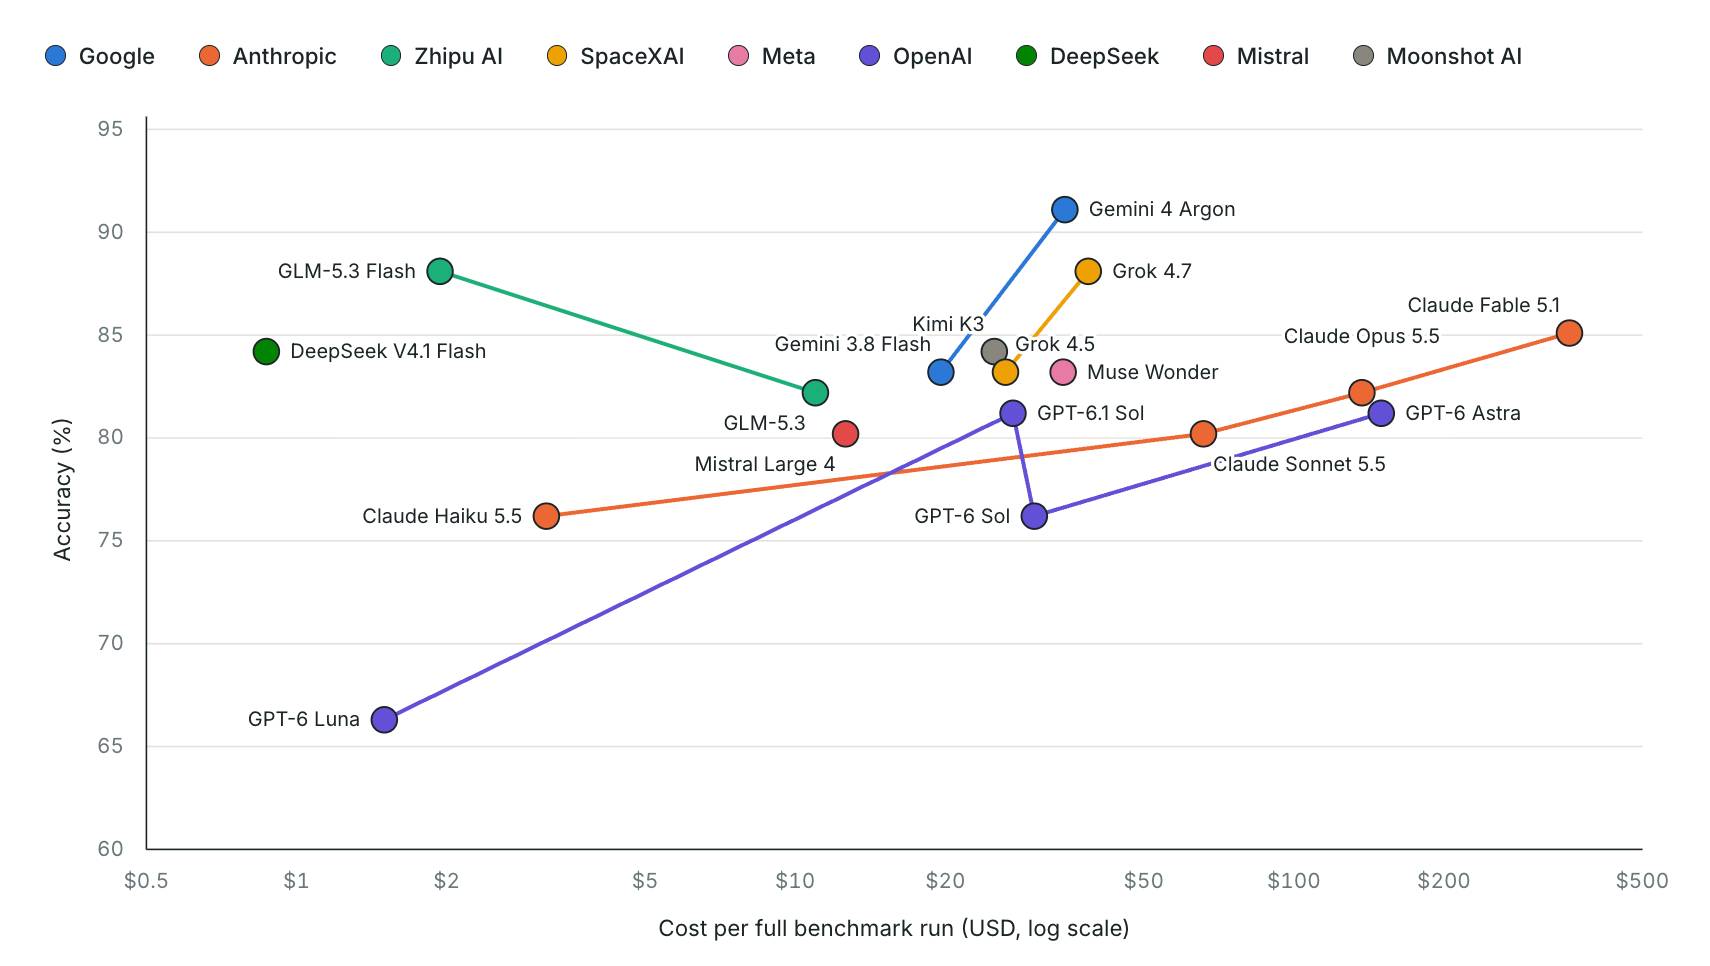
That puts Argon ahead of GLM-5.3 Flash and Grok 4.7, which both scored 88.1%, and Claude Fable 5.1 at 85.1%. It also puts some distance between Argon and Gemini 3.8 Flash, which scored 83.2% in the same benchmark.
Key findings
- Gemini 4 Argon scored 91.1%, the highest overall score in the current benchmark.
- It led or tied for the lead in five of the eight accounting areas tested.
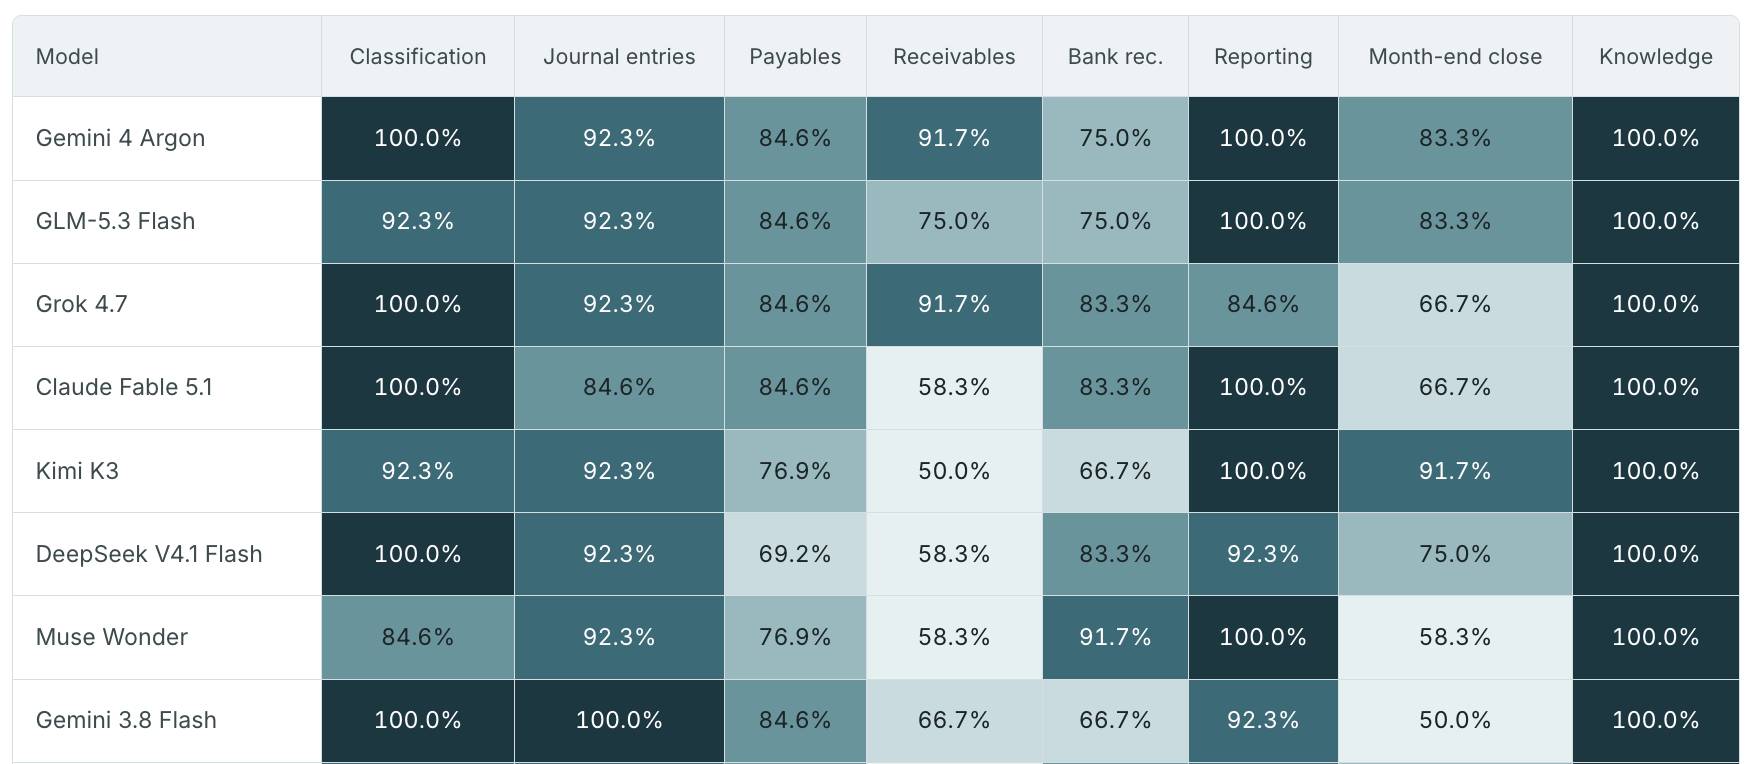
- It scored 100% in transaction classification, financial reporting, and accounting knowledge.
- It reached 82.1% on hard tasks, tied for the strongest result in the benchmark.
- Argon was also the most consistent model tested, passing 86.1% of tasks in all three runs.
- Its biggest weakness was bank reconciliation, where it scored 75% compared with Muse Wonder’s 91.7%.
Argon won on breadth
Some models in the benchmark are exceptionally good at one or two accounting workflows. Argon’s advantage was that it performed near the top across almost all of them.
It scored:
- 100% in transaction classification
- 92.3% in journal entries
- 84.6% in accounts payable
- 91.7% in accounts receivable
- 75.0% in bank reconciliation
- 100% in financial reporting
- 83.3% in month-end close
- 100% in accounting knowledge
Accounts receivable is one of the clearest examples. Scores in that category currently range from 41.7% to 91.7%, and Argon finished at the top alongside Grok 4.7. It also posted perfect scores in financial reporting and transaction classification.
The result is a model without many obvious weak spots. Argon did not lead every category, but it stayed competitive across almost all of them, which is ultimately what pushed it to #1 overall.
It was also the most consistent model we tested
The benchmark runs every model through the same 101 tasks three times. Alongside overall accuracy, we track how often each model passes the same task in all three runs.
Argon had the highest consistency score in the benchmark at 86.1%.
That compares with 80.2% for Claude Fable 5.1, 76.2% for GLM-5.3 Flash, and 74.3% for Grok 4.7. Grok and GLM came relatively close to Argon on overall accuracy, but their results moved around more between runs.
Google fixed some of Gemini 3.8 Flash’s biggest gaps
Gemini 3.8 Flash was already strong in several parts of the benchmark. It scored 100% in transaction classification and journal entries, and 92.3% in financial reporting.
Its weaker results came in some of the operational accounting categories. Argon made its biggest gains there.
Compared with Gemini 3.8 Flash:
- Accounts receivable increased from 66.7% to 91.7%.
- Month-end close increased from 50% to 83.3%.
- Bank reconciliation increased from 66.7% to 75%.
- Financial reporting increased from 92.3% to 100%.
- Accounts payable stayed flat at 84.6%.
- Journal entries fell from 100% to 92.3%.
Those changes helped move Google from 83.2% overall with Gemini 3.8 Flash to 91.1% with Argon.
Interestingly, Argon did not improve on its predecessor when we isolated the hardest questions. Both models passed 82.1% of hard tasks. The larger gains came from reducing misses elsewhere in the benchmark, particularly on medium-difficulty tasks and in workflows such as receivables and close.
Where Argon still struggled
Bank reconciliation remains Argon’s clearest weakness. It scored 75%, well below Muse Wonder at 91.7% and behind Grok 4.7 and DeepSeek V4.1 Flash at 83.3%.
Month-end close was another area where another model came out ahead. Argon scored 83.3%, while Kimi K3 reached 91.7%.
So while Argon has the strongest combined result in the benchmark, that does not mean it’s the strongest choice for every individual accounting workflow.
The same pattern appears elsewhere in the leaderboard. Muse Wonder is unusually strong at reconciliation. Kimi K3 leads month-end close. Gemini 3.8 Flash is still the only model in the current benchmark with a perfect score on journal entries.
For now, Argon’s advantage is that it gets closer to the top across more of those workflows at the same time.
See the full DualEntry Accounting AI Benchmark to compare Gemini 4 Argon with every model we’ve tested.
See the full power of DualEntry in 30 minutes
John Iwuozor leads content, finance, and research at DualEntry. He writes for the people who actually close the books: controllers running month-end, CFOs weighing an ERP migration, accountants buried in reconciliations. Before DualEntry he spent five years covering B2B SaaS and fintech for Forbes Advisor, Ramp, and Infosecurity Magazine. He builds every piece on primary data, including benchmarks, practitioner interviews, and product testing, rather than recycled advice. He is also an avid chess player.