Don't worry! The contents here will appear on the published page.
Claude Fable 5.2 Scored Lower Than Fable 5.1 on Our Accounting Benchmark
John Iwuozor
Content Lead, Finance and Research
John Iwuozor
Content Lead, Finance and Research
John Iwuozor leads content, finance, and research at DualEntry. He writes for the people who actually close the books: controllers running month-end, CFOs weighing an ERP migration, accountants buried in reconciliations. Before DualEntry he spent five years covering B2B SaaS and fintech for Forbes Advisor, Ramp, and Infosecurity Magazine. He builds every piece on primary data, including benchmarks, practitioner interviews, and product testing, rather than recycled advice. He is also an avid chess player.
Learn about our editorial policies.
Last updated
November 9, 2026
Reviewed by
Summarize this article


TL;DR
Anthropic has released Claude Fable 5.2, but its latest model didn't outperform its predecessor in our accounting tests.
We ran Fable 5.2 through the DualEntry Accounting AI Benchmark, which evaluates leading AI models on 101 accounting tasks across eight areas, including journal entries, accounts payable, accounts receivable, bank reconciliation, financial reporting, and month-end close.
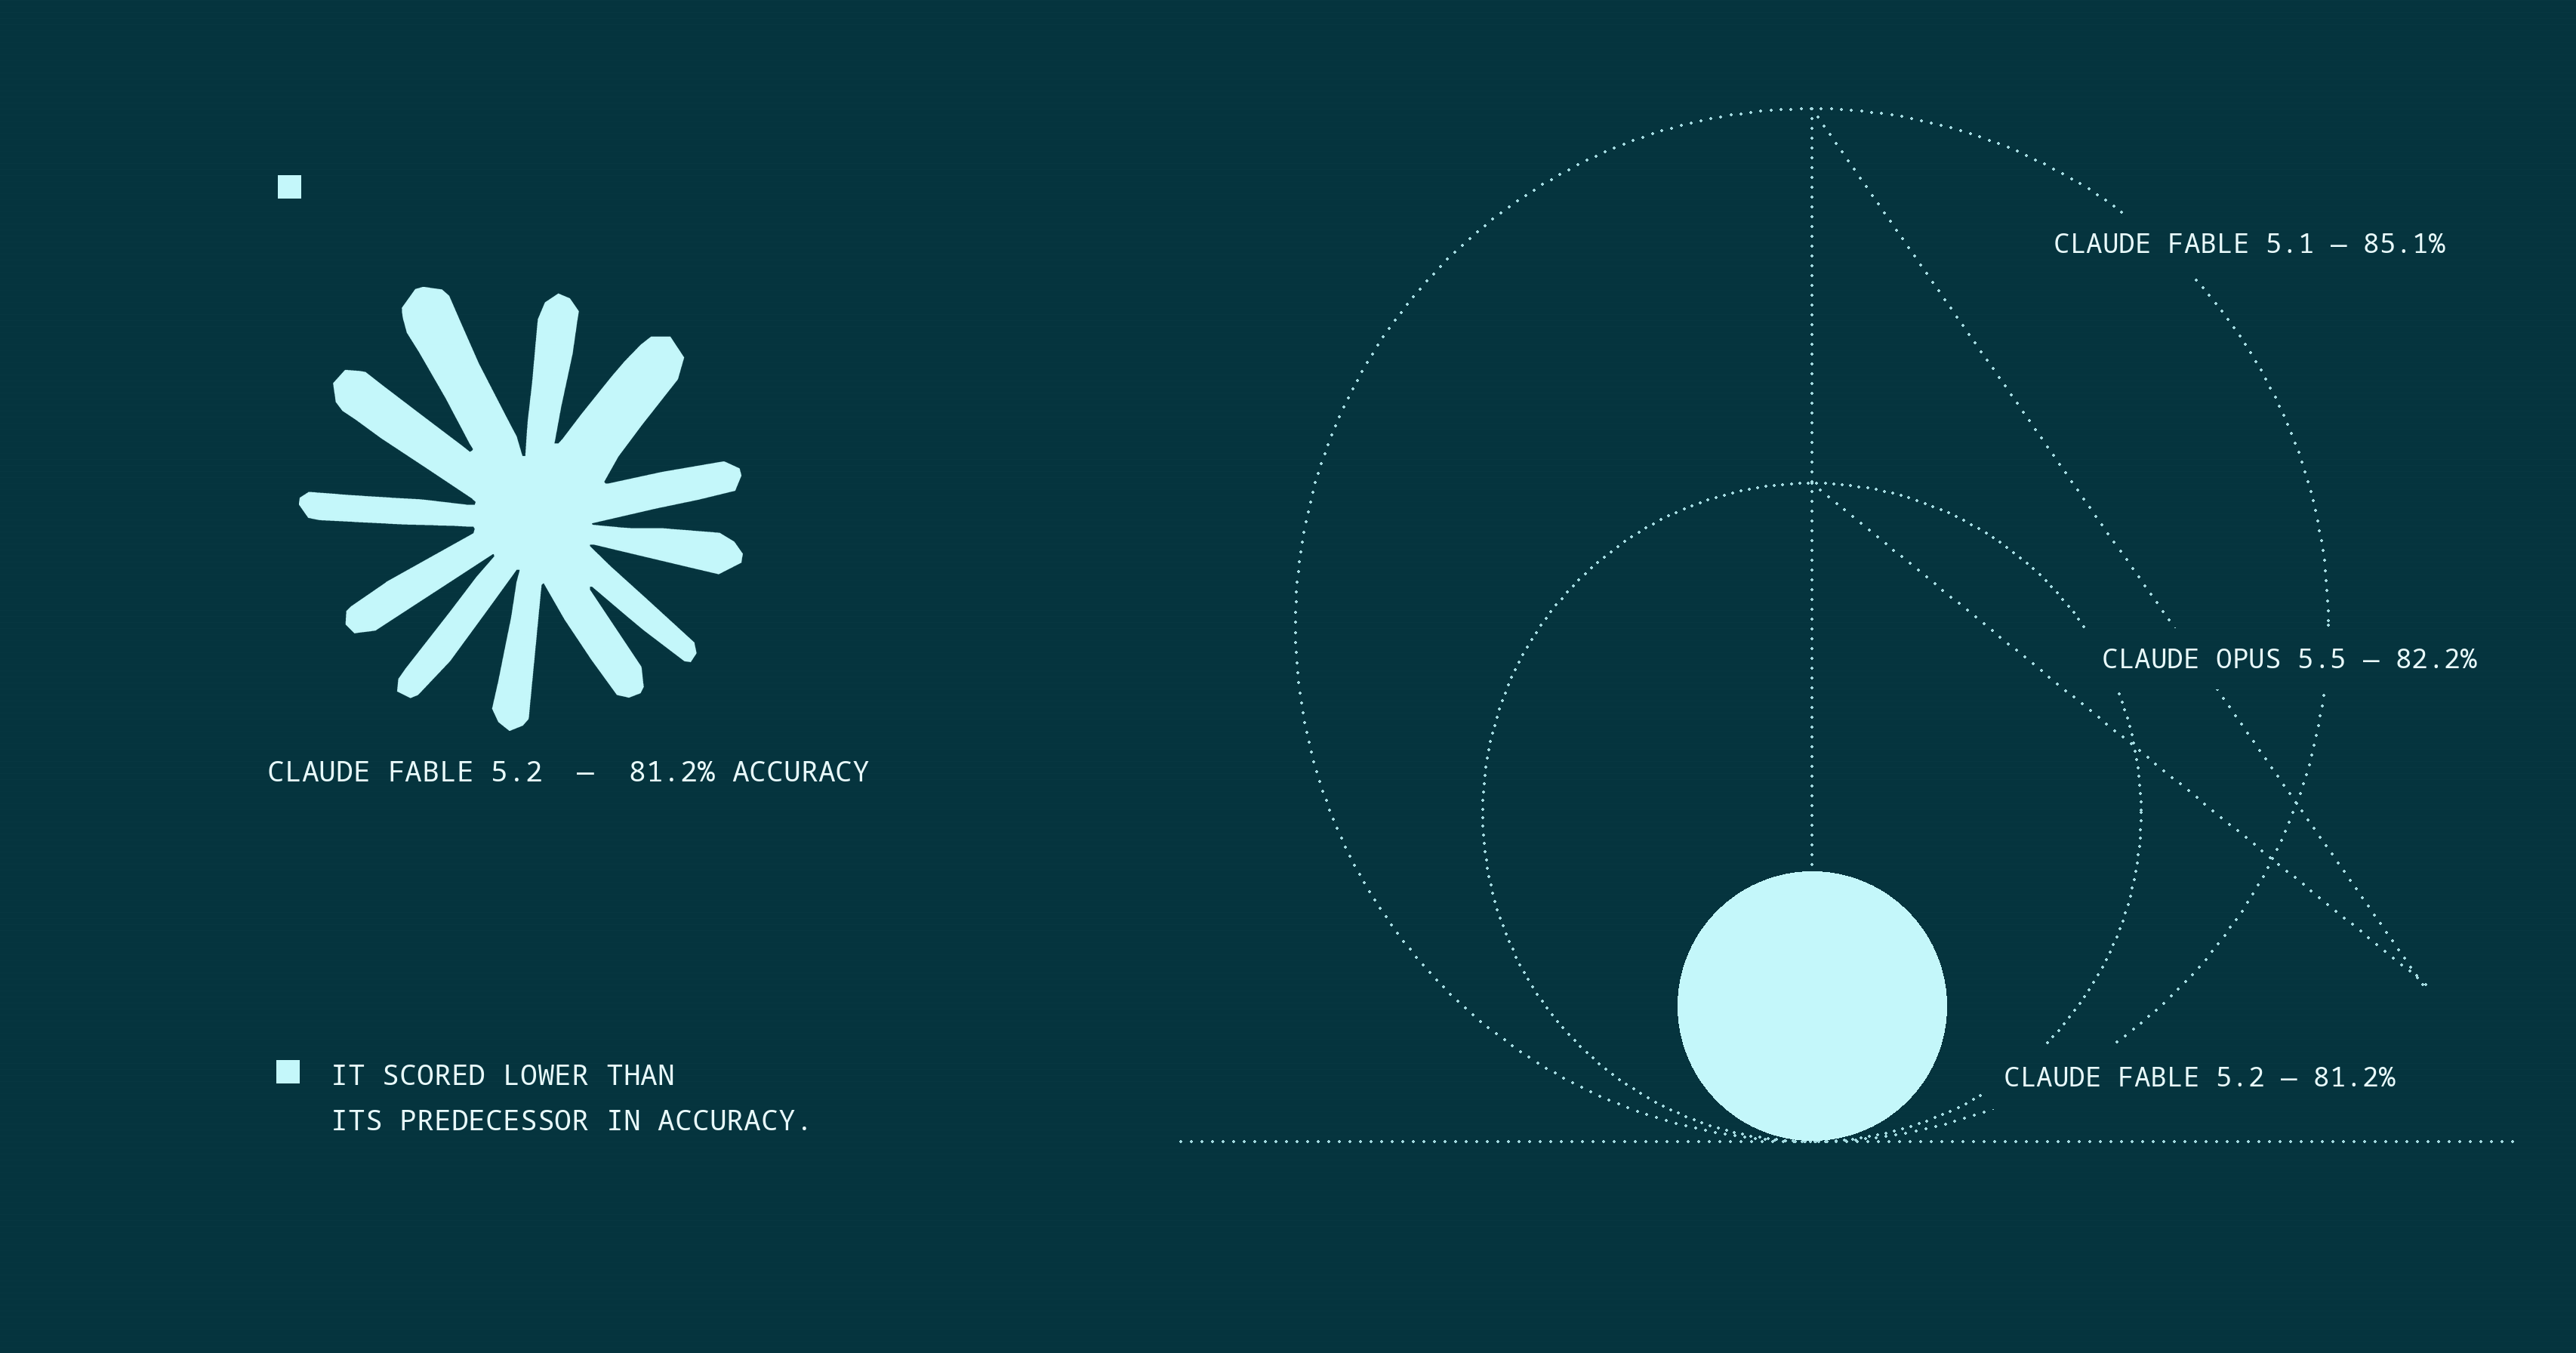
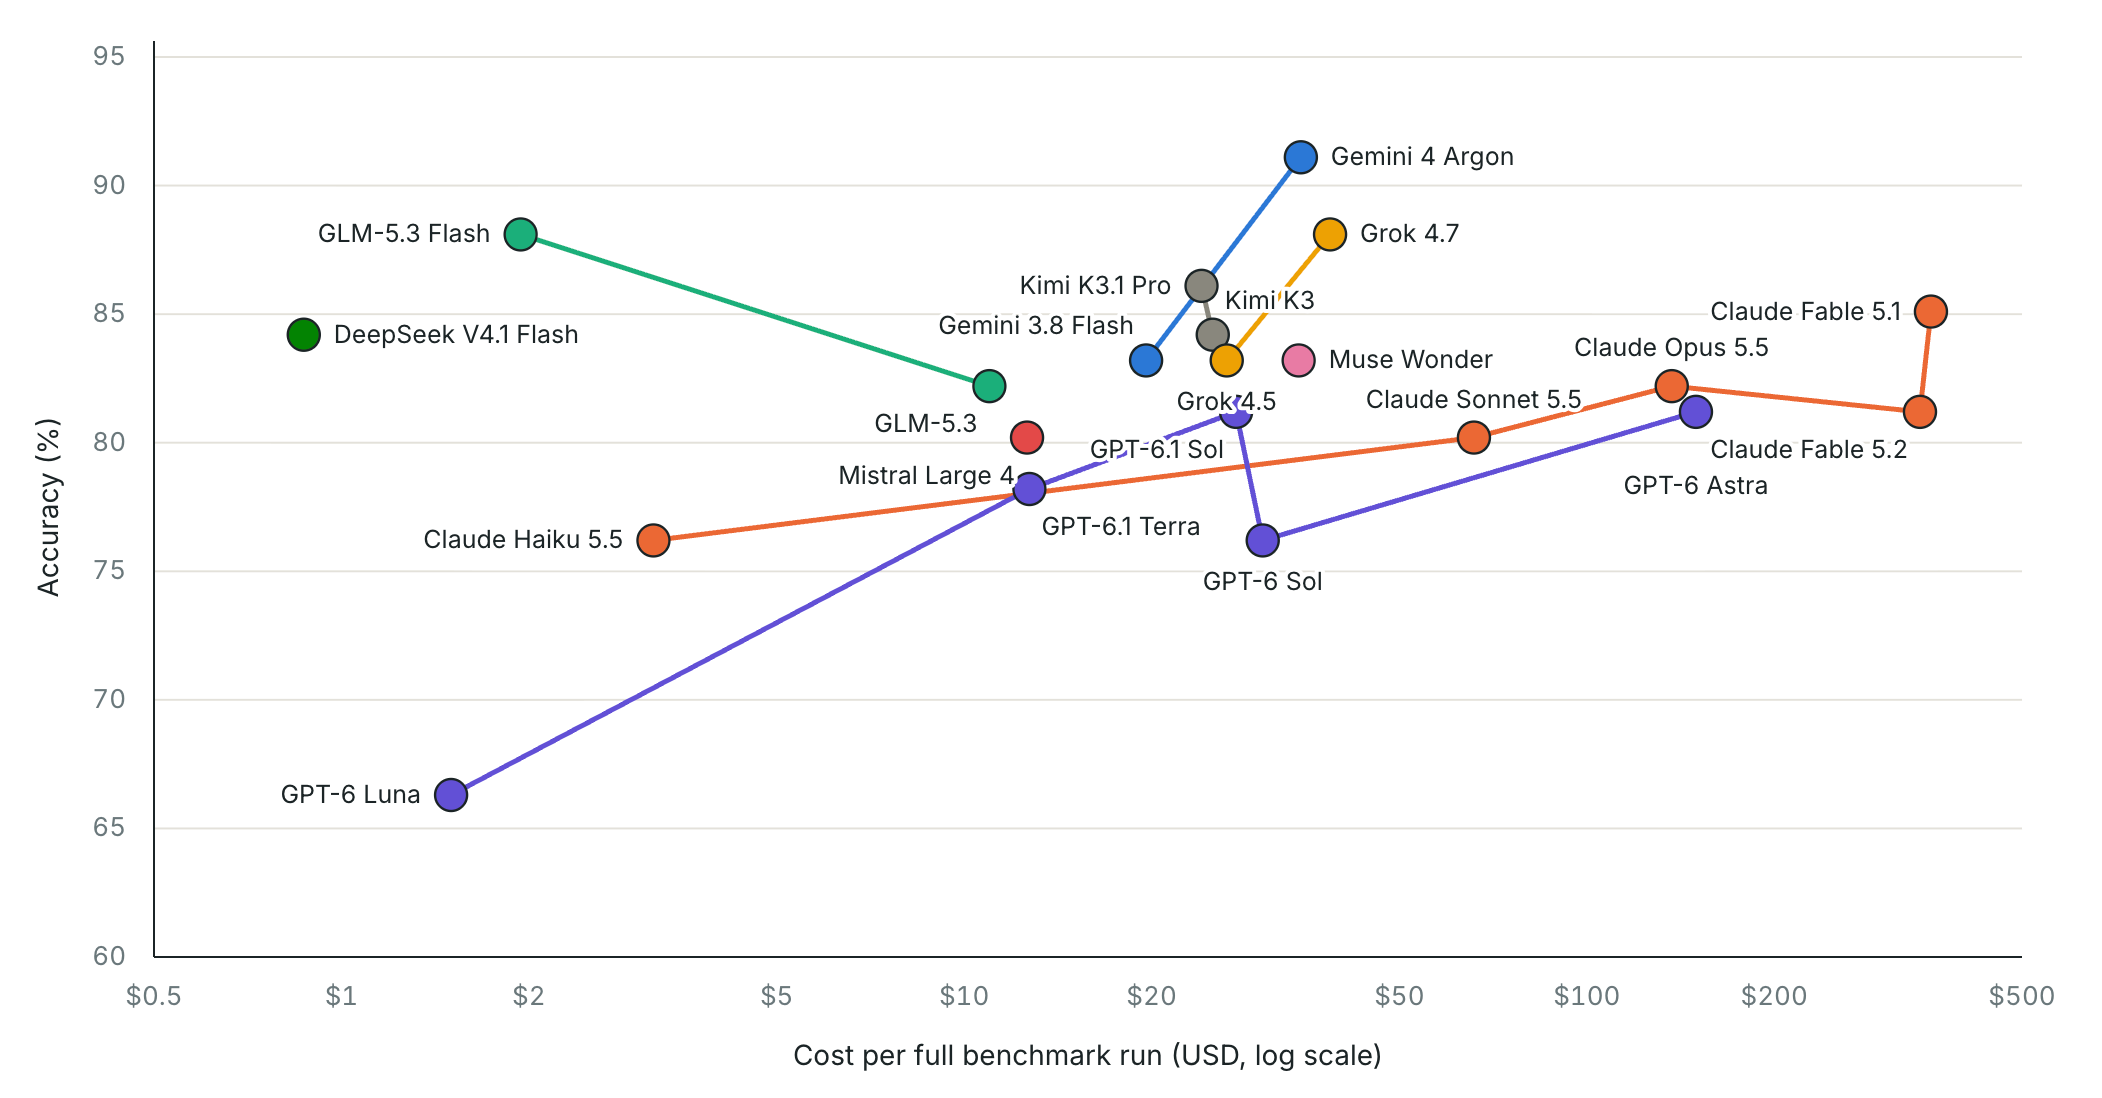
Fable 5.2 scored 81.2% accuracy, compared with 85.1% for Fable 5.1, a decline of 3.9 percentage points.
That puts it behind Gemini 4 Argon (91.1%), Kimi K3.1 Pro (86.1%), and Claude Opus 5.5 (82.2%).
Key findings
- Claude Fable 5.2 scored 81.2%, compared with 85.1% for Fable 5.1.
- It achieved 100% accuracy in transaction classification and accounting knowledge.
- Journal entries, accounts payable, and financial reporting followed at 84.6% each.
- Accounts receivable was its weakest area at 33.3%.
- It scored 70% on hard tasks, compared with 86% on easy tasks.
- Its consistency score was 76.2%, below Fable 5.1 at 80.2%.
- Fable 5.2 averaged $1.13 per task, slightly cheaper than Fable 5.1 ($1.18).
Where Fable 5.2 performed best
Fable 5.2's strongest results came in transaction classification and accounting knowledge, where it scored 100% in both categories.
Across all eight accounting areas, it scored:
- 100% in transaction classification
- 84.6% in journal entries
- 84.6% in accounts payable
- 33.3% in accounts receivable
- 83.3% in bank reconciliation
- 84.6% in financial reporting
- 75% in month-end close
- 100% in accounting knowledge
The model passed all 13 tasks in transaction classification and accounting knowledge, alongside 11 of 13 tasks each in journal entries, accounts payable, and financial reporting.
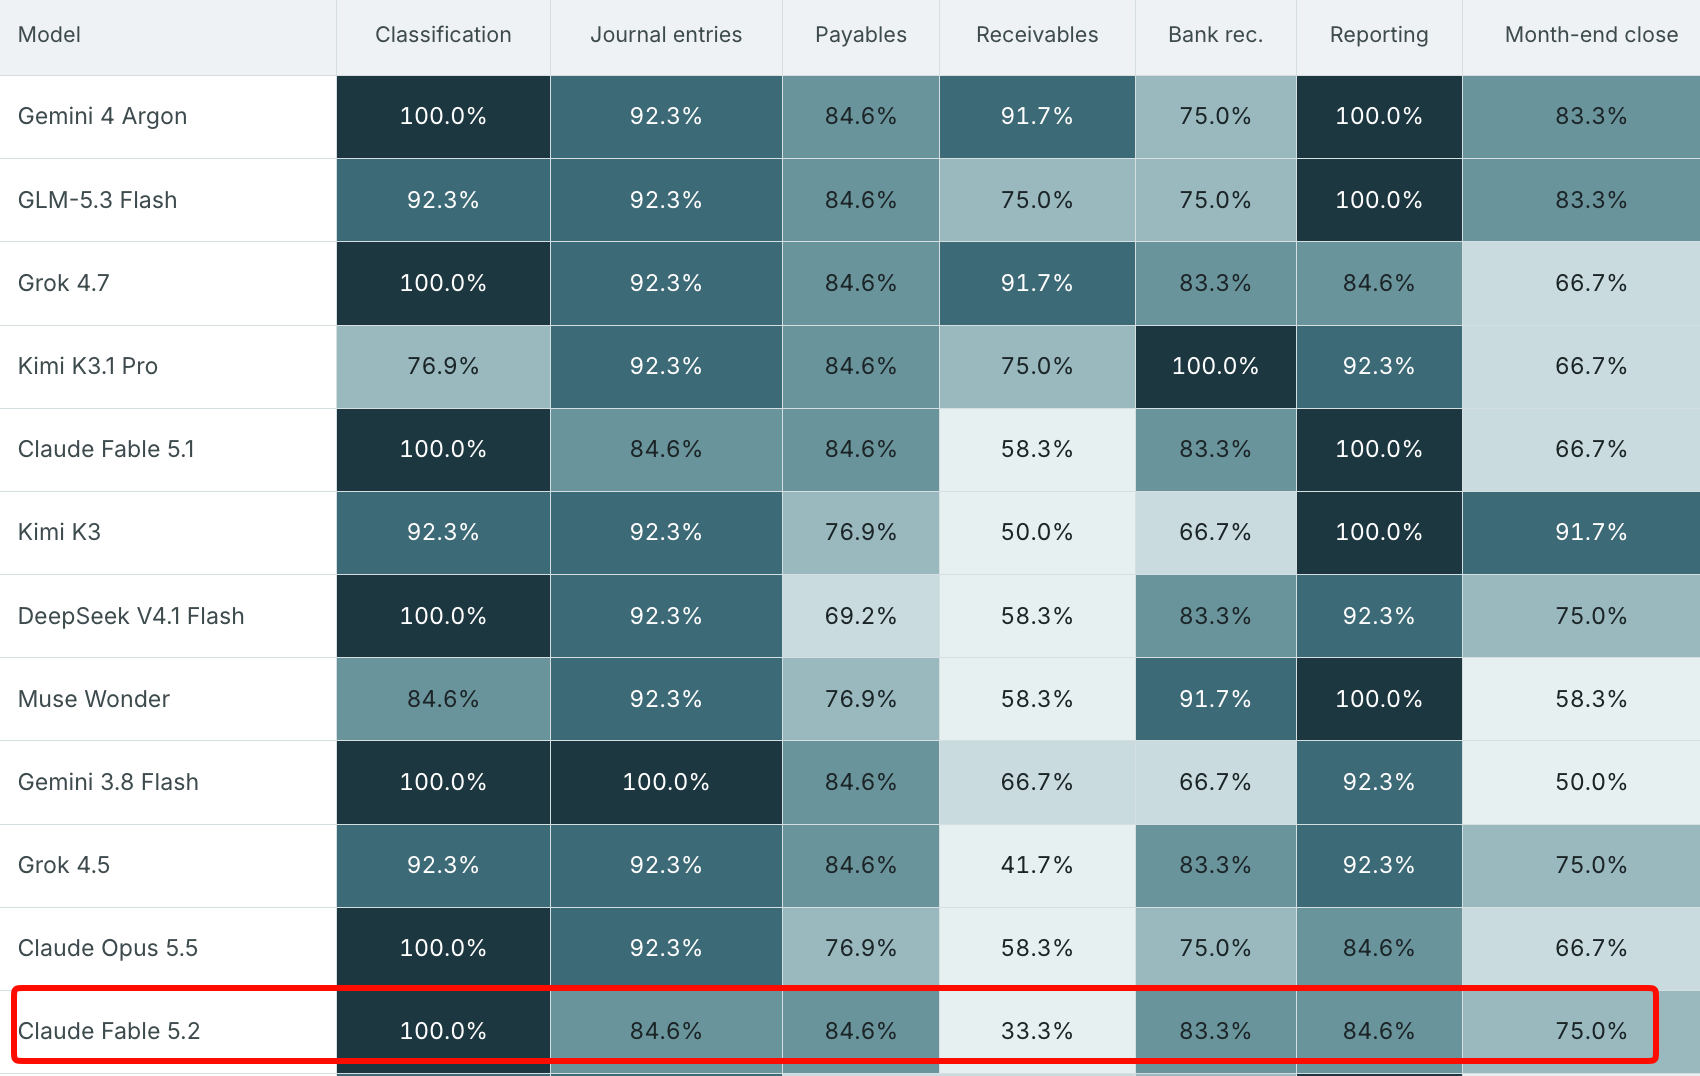
Its performance was considerably weaker in accounts receivable, where it scored 33.3%.
How Fable 5.2 compares with other models
Fable 5.2 trails other leading models:
The decline is particularly interesting given Fable 5.2's stronger performance on broader reasoning, coding, and agentic benchmarks.
On our accounting benchmark, however, Fable 5.1 remains the stronger of the two.
Fable 5.2 was also less consistent
The benchmark runs every model through the same 101 tasks three times. We measure consistency by how often a model passes the same task in all three attempts.
Fable 5.2 scored 76.2% on consistency, compared with 80.2% for Fable 5.1 and 86.1% for Gemini 4 Argon.
Performance also varied by difficulty:
- Easy tasks: 86%
- Medium tasks: 82%
- Hard tasks: 70%
Where Fable 5.2 stands
Fable 5.2 fell behind its predecessor on both accuracy and consistency. Although it performed well in transaction classification, accounting knowledge, and financial reporting, weaker results in accounts receivable kept it below the benchmark leaders.
See the full DualEntry Accounting AI Benchmark to compare accuracy, consistency, cost, and speed across leading AI models.
See the full power of DualEntry in 30 minutes
John Iwuozor leads content, finance, and research at DualEntry. He writes for the people who actually close the books: controllers running month-end, CFOs weighing an ERP migration, accountants buried in reconciliations. Before DualEntry he spent five years covering B2B SaaS and fintech for Forbes Advisor, Ramp, and Infosecurity Magazine. He builds every piece on primary data, including benchmarks, practitioner interviews, and product testing, rather than recycled advice. He is also an avid chess player.